SWEEPICK / DAPIER · 2026.10.27
CUSTOM ACT V1
데이터 수집 → 학습 → 추론 → 분석
전형주 · 모방학습·시뮬레이션·Sim-to-Real·데이터 검증 주담당
학습한 행동을 작업 결과로 확인하기
SWEEPICK은 청소 경로의 작은 물체를 옮기는 저비용 양팔 모바일 매니퓰레이터입니다. 이 사례는 팀 프로젝트의 CUSTOM ACT V1 SIM 수집·학습·평가 자료를 따라, 데이터가 어떻게 정책과 작업 결과로 이어졌는지 설명합니다. ACT는 팀원과 공동 개발·검증했습니다. 제 주 담당은 모방학습·시뮬레이션·Sim-to-Real과 데이터 검증이며 VSLAM에는 협업으로 참여했습니다.
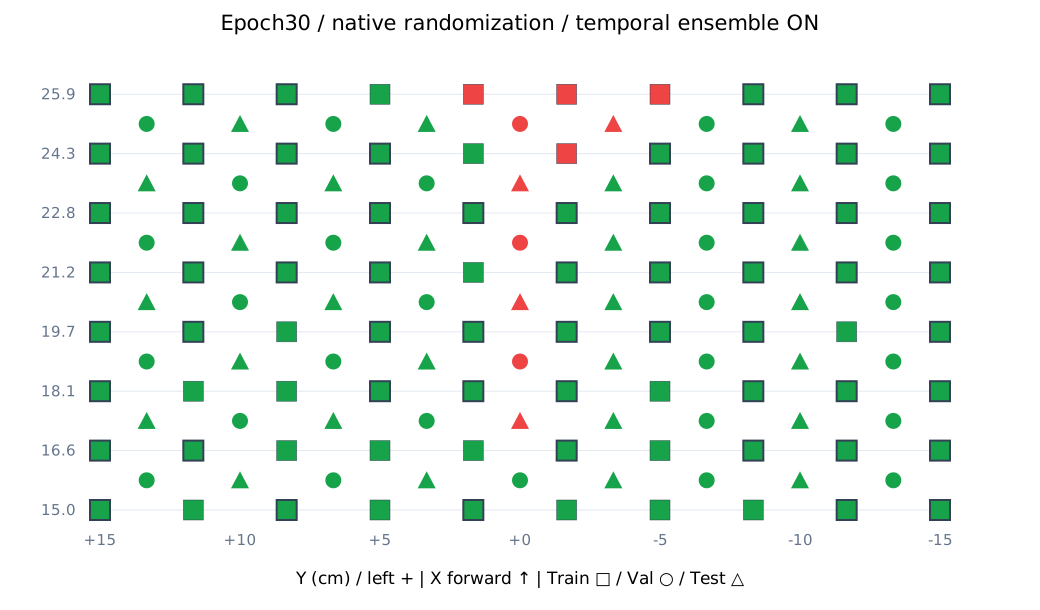
고정 epoch30 모델의 143위치 평가에서 132/143(92.3%), Test는 27/31(87.1%)이었습니다. 각 위치 1회, temporal ON(k=.01), Lift≥30 mm→Stow→접촉·상승 상태의 2초 Hold라는 조건에서 얻은 결과입니다. 별도 200 epoch 학습의 오프라인 결과와 함께 읽되 모델별 결과는 구분합니다.
SWEEPICK is a low-cost bimanual mobile manipulator that relocates small clutter before cleaning. This case follows the team project’s CUSTOM ACT V1 SIM collection, training and evaluation artifacts from data to policy and task outcome. I jointly developed and evaluated ACT with a teammate. My main responsibilities are imitation learning, simulation, Sim-to-Real and data validation; I also contributed collaboratively to Visual SLAM.
A fixed epoch30 model completed 132/143 positions (92.3%), including 27/31 (87.1%) on Test. Each position was tried once, with temporal ON(k=.01) and a Lift≥30 mm→Stow→two-second elevated/contact Hold criterion. The separate 200-epoch offline training result is presented alongside it, with model-specific outcomes kept distinct.
01 · 데이터 수집
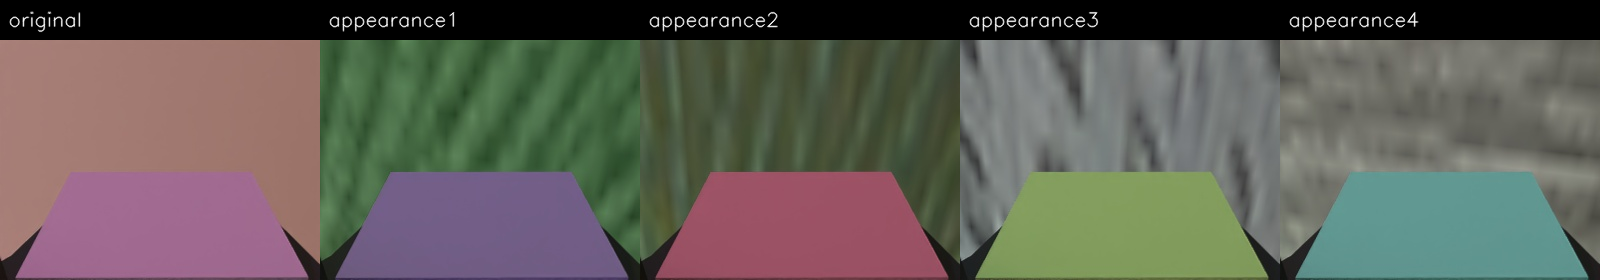
공동 ACT 실험에서 원본 113개 기준 궤적의 동작을 보존하고 손목 RGB의 블록색·배경·테이블 텍스처·조명을 바꾼 외형 4개를 추가해 565뷰(원본113+452)를 구성했습니다. 같은 궤적의 상태·행동·시각·물체좌표와 head depth/PCD 정합을 검사하며, 외형만 달라진 데이터를 독립 동작으로 세지 않았습니다.
기준 궤적 Train59 / Val29 / Test25를 먼저 나누고, 같은 궤적의 변형은 같은 split에 유지했습니다. 최종 뷰는 Train295 / Val145 / Test125입니다. Test 시연 payload는 학습에서 제외해 보존했습니다.
In our collaborative ACT experiments, we preserved the motion of 113 base trajectories and added four appearances per trajectory by varying wrist-RGB block color, backgrounds, table textures and lighting: 565 views (113 originals + 452 additions). Joint/action/time/object-coordinate and head-depth/PCD alignment are checked. Appearance variants are counted as views rather than independent motions.
Base trajectories were split into Train59 / Val29 / Test25 before augmentation; variants stay in the same split. The resulting view counts are Train295 / Val145 / Test125. Test demonstration payloads remain excluded from training.
02 · 학습
양손목 RGB의 shared ResNet18·1×1 projection과 head PCD·관절 state를 연결하는 커스텀 ACT를 사용했습니다. 설정은 hidden256, chunk20, state/action12, KL10이며 추론 prior는 z=0입니다.
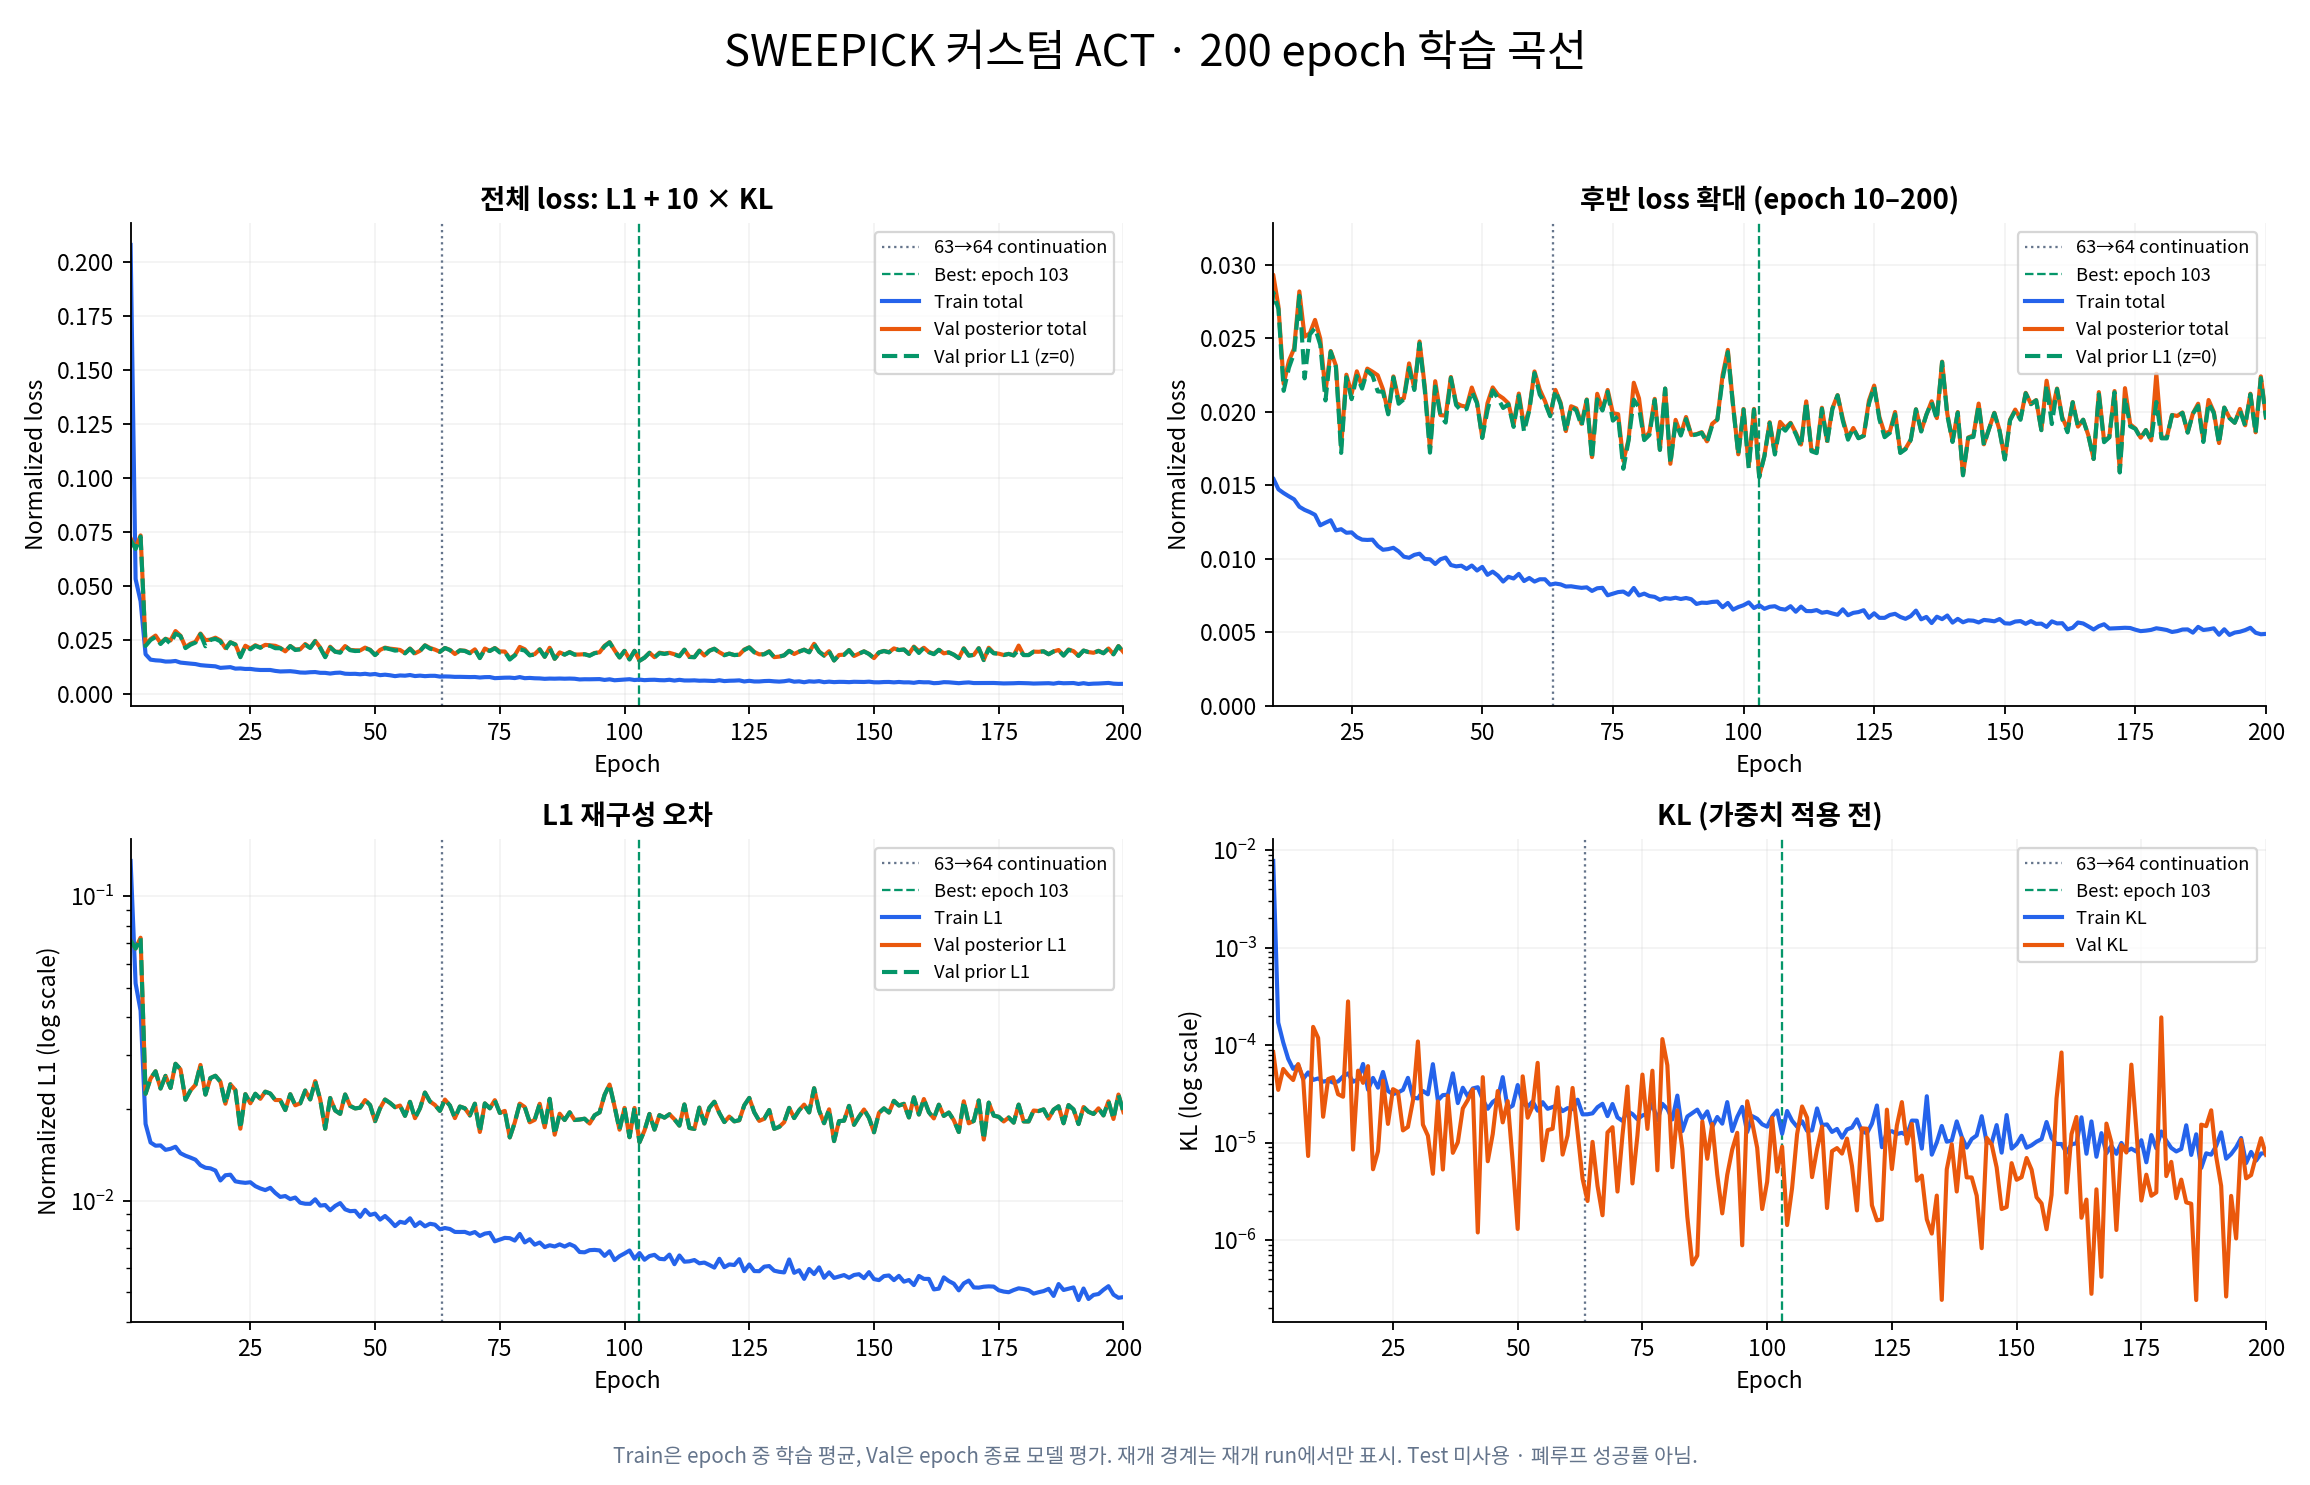
공동 ACT 실험에서 200 epoch 학습을 완료했습니다. epoch1–3은 batch4, epoch4–200은 batch32이고 epoch63에서 재개한 실행을 포함합니다. Val prior 정규화 L1의 best는 epoch103 · 0.015534, epoch200 값은 0.019515입니다. 이 최종 학습 모델의 폐루프 평가는 자료에 없습니다.
Custom ACT connects shared wrist-RGB ResNet18 features and a 1×1 projection with head PCD and joint state. The configuration uses hidden256, chunk20, state/action12 and KL10; inference uses the prior z=0.
Our collaborative ACT training completed 200 epochs. Epochs1–3 use batch4 and epochs4–200 use batch32, including a run resumed after epoch63. Best Val prior normalized L1 is 0.015534 at epoch103; epoch200 is 0.019515. This final training model has no closed-loop evaluation in the source artifacts.
03 · 추론과 폐루프 평가
epoch30 checkpoint를 고정하고 temporal ensemble ON(k=.01)으로 143위치를 각1회 실행했습니다. 정책 입력은 관절q·head PCD·양손목RGB·prior z=0이며, 정답 행동·phase·물체 정답 pose는 정책에 넣지 않았습니다.
블록색·테이블/벽 텍스처·조명은 랜덤화했고 40 mm 물체의 크기·yaw·물성·카메라 보정은 고정했습니다. 성공은 Lift≥30 mm → 실측 Stow 오차≤.025 rad → 접촉·상승 상태에서 물리2초 Hold입니다. Test 결과로 평가 모델을 바꾸거나 선택하지 않았습니다.
The epoch30 checkpoint stays frozen, running temporal ensemble ON(k=.01) once at each of 143 positions. Inputs are joint q, head PCD, both wrist RGB streams and prior z=0; ground-truth actions, phase and object pose are excluded from policy inputs.
Block color, table/wall textures and lighting vary; 40 mm object size, yaw, physics and camera calibration stay fixed. Success requires Lift≥30 mm → measured Stow error≤.025 rad → two physics seconds of elevated/contact Hold. Test results were not used to change or select the evaluated model.
| 평가 구분 | 성공 / 시도 | 관측 비율 |
|---|---|---|
| 전체 | 132 / 143 | 92.3% |
| Train | 76 / 80 | 95.0% |
| Val | 29 / 32 | 90.6% |
| Test | 27 / 31 | 87.1% |
이 비율은 고정 SIM 조건의 위치별1회 관측입니다. 실물·전체 청소·위치별 반복 신뢰도·양팔 동시 조작의 성공률을 뜻하지 않습니다.
04 · 분석
실패11곳은 grasp/lift7 · stow4로 나눴습니다. 실패 위치에서 예측 청크·명령 관절·실측 관절·phase·영상을 함께 읽고, temporal aggregation이 같은 target시점의 후보와 가중치를 어떻게 결합하는지 저장CSV로 재구성했습니다. 원자료 대조에서 target 정렬 오류0, 가중치 최대오차1.85e−8, 명령 복원 최대오차1.84e−7 rad를 확인했습니다. 이는 저장된 구현 출력과 계산의 일치를 확인한 결과입니다.
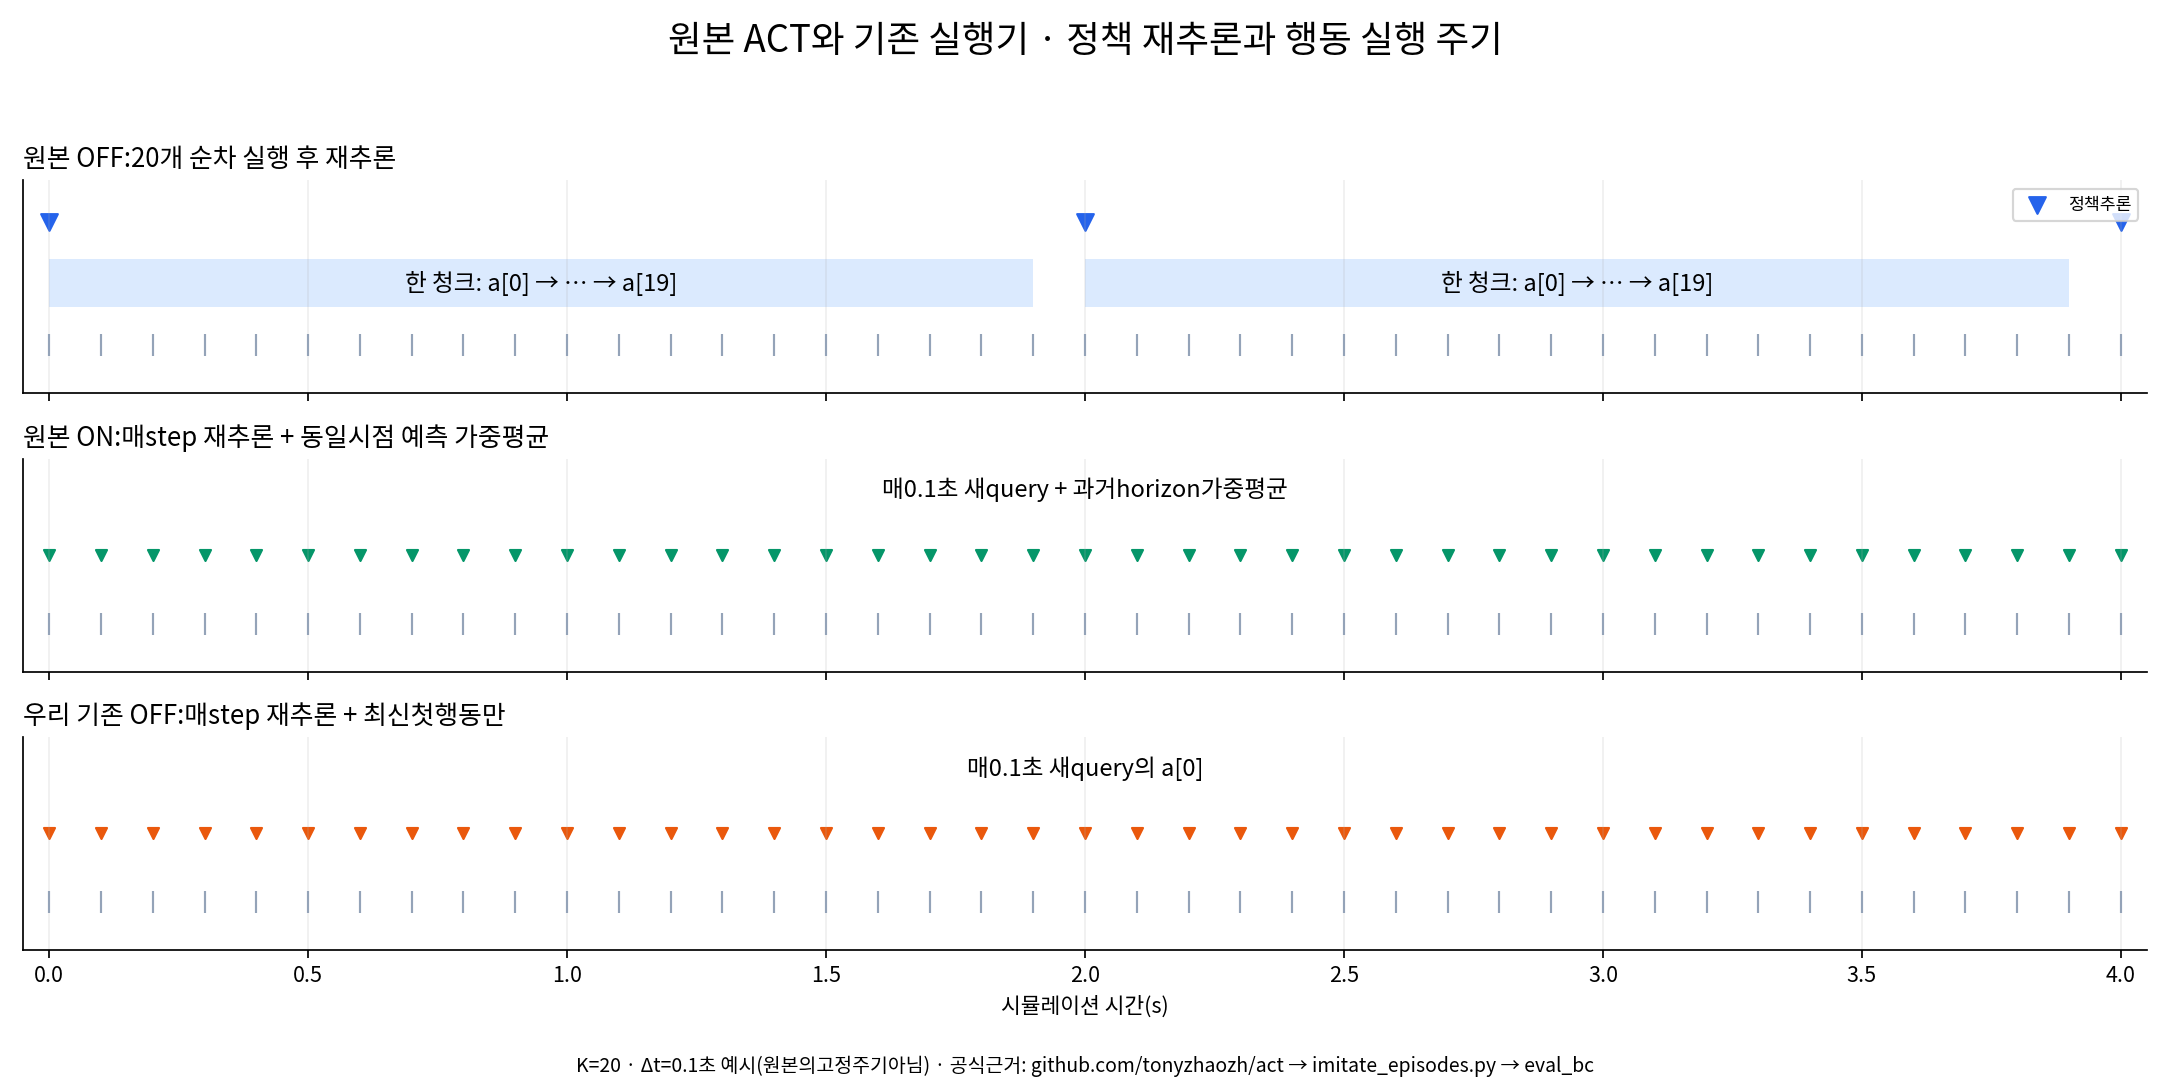
동일 epoch30·Val mid00_00 비교에서는 ON이 Lift→Stow→Hold를 마쳤고 기존 first-action-only OFF는 8.4초 관찰 뒤 중단됐습니다. 기존 OFF는 원본 ACT의 chunk sequential OFF와 실행 방식이 다릅니다. 원본 OFF는 미실행이므로, 이 단일 비교만으로 ON의 일반적 성능 향상이나 필수성을 결론내리지 않습니다.
The 11 failures split into seven grasp/lift and four stow cases. Predicted chunks, commanded/measured joints, phase and video are read together. Saved CSVs reconstruct how temporal aggregation aligns candidates at the same target time and weights them. The source audit found zero target-alignment errors, maximum weight error1.85e−8 and command reconstruction error1.84e−7 rad. These checks verify agreement with saved implementation outputs.
At epoch30 / Val mid00_00, ON completed Lift→Stow→Hold while the existing first-action-only OFF was stopped after 8.4 seconds of observation. That OFF schedule differs from original ACT’s sequential-chunk OFF, which was not run. This single comparison does not establish a general performance gain or the necessity of ON.
자료 출처와 공개 다운로드
이 페이지는 지정된 CUSTOM_ACT_V1_standalone_20261027.html의 내장 자료를 기준으로 구성했습니다. 시뮬레이터 재실행이 아니라 원 attempts CSV143행·episode JSON143개·학습로그와 곡선·앙상블 CSV를 대조한 집계입니다. 팀 실험의 데이터·외부 라이브러리·협업 코드를 제 단독 저작물로 주장하지 않습니다.
This page follows the embedded artifacts in CUSTOM_ACT_V1_standalone_20261027.html. Counts were checked against 143 attempts-CSV rows, 143 episode JSONs, training logs/curves and ensemble CSVs; the simulator was not rerun. Team data, external libraries and collaborative code are credited as project artifacts rather than sole-authored work.
- 원자료 HTML SHA-256
b0d3b524f57b6ae4e2f01c2533bab8c0ca90a532c99112a13bdfdf9092fa599f- 평가 epoch30 checkpoint SHA-256
032aab674bdbe83a3e75ebf793fc98026ea0c382f994f40ef05f5c4730ab0cf7
CSV/JSON은 개인 경로·실행 명령을 제외한 공개용 요약입니다. 그림과 영상은 선별한 원자료이며, 원본 전체 HTML·원시 실행 JSON은 배포하지 않습니다.
원 미디어 경로와 SHA-256
- collection-appearances.png
CUSTOM_ACT_V1/outputs/SWEEPICK_robotwin_color_paired5_20261026/pilot_five_appearances.png2f204eec5b9593cfa32c46d34c04864a53f41f6b58c55704de5b2929ea327390- training-curves.png
CUSTOM_ACT_V1/outputs/SWEEPICK_paired_act200_batch32_resume63_20261026/visualization/01_learning_curves.pngab86e85ae2f69211c6a9859cd55f6213dffd214fc551f3a0911fcb3af15d5d18- evaluation-workspace.svg
CUSTOM_ACT_V1/outputs/SWEEPICK_ACT30_randomized143_20261026/workspace.svge9f32de9dafd43f93ae65c7e30c9968b1cd178d99e474219e1539ef7e3bc232e- control-schedules.png
CUSTOM_ACT_V1/outputs/SWEEPICK_epoch30_temporal_comparison_20261026/05_control_schedules.png5bb4036b3e6575e03e2ba5804fe2de1453c4a9f26bbd376cf5c178807a85cb48- sim-test-mid00_01.mp4
CUSTOM_ACT_V1/outputs/SWEEPICK_ACT30_randomized143_20261026/episodes/mid00_01/preview.mp4caa1a9c6eadf6f4419398ec0574498e2f7ae6f3905807a194ae4e972078ceec2
후속 실물 트랙과 참고·Legacy
기존 실물 트랙: Native 교사 콘솔120/198(10/18–26), TJJ v2 학습46/검증7·3.30°(epoch690), DAgger 교정16개(10/23–25)를 별도 기록으로 보존합니다.
10/27 후속은 ACT30과 실물 실행기의 관측·12축 절대행동 계약 정합입니다. IR2 정지 shadow는 30초·양팔 각300prefix에서 위반0·모터쓰기0을 확인한 제한 검사입니다. full180s=false/all_pass=false이므로 전체 검증 통과나 새 실물 파지 성공으로 쓰지 않습니다.
초기 epoch12 관찰, 단일 위치 ON/OFF, 과거 위치 계획과 9월 파지 SIM·C++ MOCK 검사는 당시 기록으로 남깁니다. 전체 물체 이동·청소·복귀·도킹·충전은 SIM 구현 완료이며 실물 통합은 진행 중입니다. 작업용 OS30A와 양손목 RGB, 전면 Astra VSLAM의 역할도 구분합니다.
Separate physical track: Native teacher console120/198 (Oct18–26), TJJ v2 on46 training/7 validation runs with3.30° error(epoch690), and16 DAgger corrections(Oct23–25).
The October27 follow-up aligns ACT30 and the physical executor’s observation/12-axis absolute-action contracts. The30-second IR2 stationary shadow checked300 prefixes per arm with zero violations and zero motor writes. With full180s=false/all_pass=false, this remains a bounded check, separate from complete validation or a new physical grasp result.
Early epoch12 observations, single-position ON/OFF, older position plans, September grasp SIM and C++ MOCK checks remain historical records. Full relocation, cleaning, return, docking and charging is complete in SIM, with hardware integration ongoing. Workspace OS30A and wrist RGB serve different roles from front Astra VSLAM.