SWEEPICK · 커스텀 ACT 학습·평가
모방학습·시뮬레이션·Sim-to-Real·데이터 검증 주담당 · ACT 공동 개발·검증
청소 경로의 작은 물체를 옮기는 저비용 양팔 모바일 매니퓰레이터입니다. 팀원과 ACT를 공동 개발·검증하며 데이터 수집 → 학습 → 추론 → 분석을 함께 연결해, 예측 오차뿐 아니라 물체를 들고 수납 자세로 이동해 유지하는 실제 SIM 행동을 평가했습니다.
고정 epoch 30 · temporal ON(k=0.01) 모델은 랜덤화한 143위치에서 132/143(92.3%), 그중 Test에서 27/31(87.1%)을 기록했습니다. 위치당 1회, Lift≥30 mm→Stow→접촉·상승 상태 2초 Hold 기준입니다. 별도 200 epoch 학습 모델의 성능이나 실물 성공률과는 구분합니다.
A low-cost bimanual mobile manipulator that relocates small clutter before cleaning. I jointly develop and evaluate ACT with a teammate. Together we connect collection → training → inference → analysis, evaluating whether a policy lifts the object, reaches stow and holds it in SIM alongside prediction error.
The fixed epoch 30 model · temporal ON (k=0.01) recorded 132/143 (92.3%) across randomized positions, including 27/31 (87.1%) on Test. Each position was tried once; success required Lift≥30 mm→Stow→two seconds of elevated/contact Hold. This is separate from the 200-epoch training model and physical success.
ACT 공동 실험에서 관측·행동 정합, 궤적별 분할, 실행·실패 분석을 팀원과 함께 다뤘습니다. VSLAM에도 협업으로 참여했습니다.
수집·학습·추론·분석의 핵심
- 수집공동 ACT 실험에서 113개 기준 궤적을 보존하고 궤적당 외형 5개로 565뷰를 구성했습니다. 같은 궤적의 변형은 같은 split에 두고 관절·행동·영상·깊이의 정합을 검사했습니다.
- 학습Train 295 / Val 145뷰로 200 epoch까지 학습했고 best는 epoch 103입니다. Test 125뷰는 보존했습니다.
- 추론별도 고정 epoch 30 모델을 143위치에서 폐루프로 평가했습니다. 색·텍스처·조명은 랜덤화하고 물체 크기·yaw·물성·보정은 고정했습니다.
- 분석실패 11곳을 grasp/lift 7곳과 stow 4곳으로 나누고, 예측 청크·관절 명령·실측·phase·영상을 연결했습니다. ON/OFF 단일 위치 비교는 실행 방식의 차이를 조사한 기록입니다.
- CollectionIn our collaborative ACT experiments, we preserved 113 base trajectories with five appearances each, producing 565 views. Variants stay in the same split; joints, actions, images and depth are checked for alignment.
- Training200 epochs using 295 Train / 145 Val views; best validation epoch 103. The 125 Test views remain held out.
- InferenceA separate fixed epoch 30 model was evaluated closed-loop at 143 positions. Color, textures and lighting vary; size, yaw, physics and calibration remain fixed.
- AnalysisSplit 11 failures into seven grasp/lift and four stow cases, connecting predicted chunks, commands, measured joints, phase and video. A single-position ON/OFF comparison investigates execution schedules.
별도 실물 트랙과 후속 Sim-to-Real
Native 자동 교사는 실물 관측·집기·이동·놓기·복귀를 반복했습니다. 10/18–26 콘솔 집계는 120/198회 성공 판정입니다. 실물 데이터 TJJ v2는 학습46/검증7 run에서 관절 예측오차 3.30°(epoch 690), 10/23–25 DAgger 교정 시연은 16개입니다. 이 기록은 새 CUSTOM ACT V1 SIM 평가와 다른 트랙입니다.
10/27 후속 작업은 ACT30과 실물 실행기의 관측·12축 절대행동 계약, 앙상블·STOP·feedback·파지 증거 경로를 맞추는 것입니다. IR2 정지 shadow는 양팔 각 300 prefix, 위반0·모터쓰기0의 제한된 점검이며 새 실물 파지 완료 기록은 아닙니다.
The Native teacher repeated physical observation, pick, transfer, place and return. The October 18–26 console reports 120/198 runs assessed successful. Physical-data TJJ v2 reached 3.30° joint prediction error (epoch 690) on 46 training / 7 validation runs; 16 DAgger corrections were collected October 23–25. These belong to a separate track from the new CUSTOM ACT V1 SIM evaluation.
The October 27 follow-up aligns ACT30 and the physical executor’s observation/12-axis absolute-action contracts, ensemble, STOP, feedback and grasp-evidence paths. The IR2 stationary shadow checked 300 prefixes per arm with zero violations and zero motor writes. It is a bounded check, separate from new physical grasp completion.
전체 시나리오와 직무 연결
청소 전 정리에서 복귀·충전까지
작은 물체를 옮긴 뒤 청소하고, 배터리가 부족하면 복귀해 도킹·충전하는 흐름을 시뮬레이션에서 구현했습니다. 실물은 상체 조작과 이동 기능을 단계별로 통합하고 있습니다. 제가 협업으로 참여한 VSLAM은 RGB-D 지도·위치 추정과 Nav2 작업영역 접근을 연결합니다. 현재 이동 모듈의 유지 담당은 별도 팀이며, 제 주력은 양팔 모방학습과 Sim-to-Real입니다.
- 시뮬레이션MuJoCo에서 관절·접촉·카메라와 조작 성공 조건을 검증합니다.
- 실물 관측·실행작업공간용 OS30A·손목 RGB를 SO-101/STS3215 Serial 상태 조회·관절 명령과 연결합니다. 관절 tick↔rad·영점·부호와 모델/실물 입출력을 대조합니다. 모바일 전면 중앙 Astra는 VSLAM용 별도 센서입니다.
- 학습 데이터·정책교사 시연의 관측·행동을 정렬하고 ACT 평가·정체 인계·DAgger 수집을 연결합니다.
- 재현 가능한 실험실행 조건·데이터 버전·실패 상태를 남겨 같은 조건에서 수정 효과를 비교합니다.
이 경험을 로봇 학습 데이터 파이프라인, 시뮬레이션 환경 구성, 정책 평가와 실물 연동 업무에 적용하고 싶습니다.
From clutter removal to return and charging
I implemented the simulation flow for relocating objects, cleaning and returning to dock and charge when the battery is low. On hardware, we are integrating arm manipulation and mobility in stages. The Visual SLAM project I contributed to collaboratively connects RGB-D mapping/localization with Nav2 workspace approach. A separate team now maintains the mobile module; my primary focus remains bimanual imitation learning and Sim-to-Real.
- SimulationValidate joints, contact, cameras and manipulation criteria in MuJoCo.
- Physical observations and executionConnect workspace OS30A and wrist RGB to SO-101/STS3215 Serial state queries and joint commands. Check joint tick↔rad mapping, zero/sign conventions and model/hardware inputs and outputs. The front-center Astra is a separate VSLAM sensor.
- Learning data and policyAlign teacher observations/actions and connect ACT evaluation, stalled-state takeover and DAgger collection.
- Reproducible experimentsRecord conditions, data versions and failure states to compare changes under the same setup.
I want to apply this experience to robot-learning data pipelines, simulation environments, policy evaluation and hardware integration.
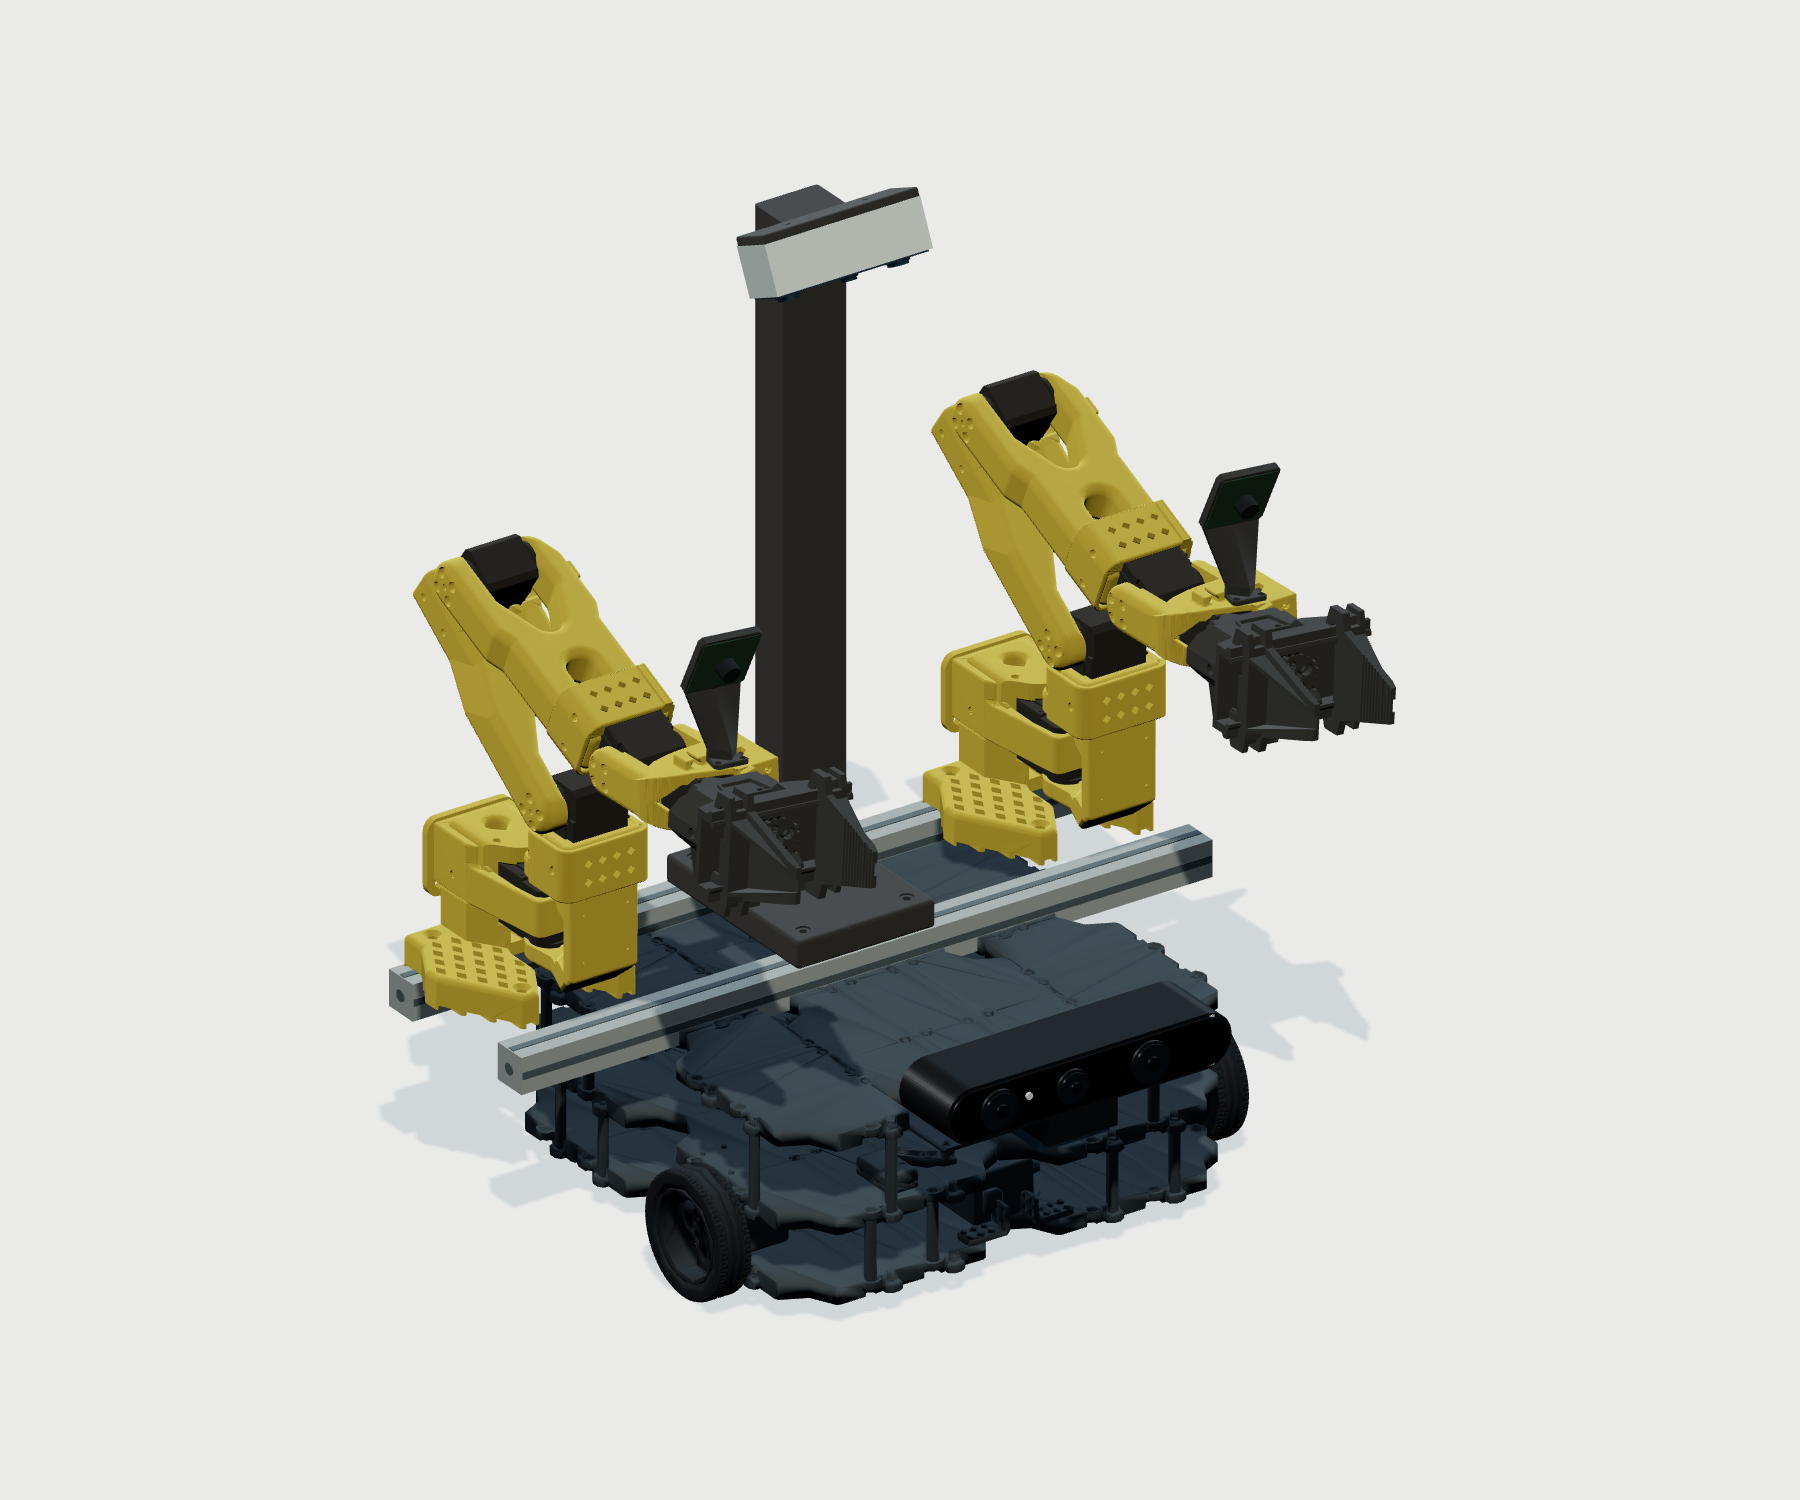
로봇 구성 3D로 보기
2026.10.01 CAD·SIM 참고 모델입니다. 양팔·작업용 OS30A·전면 Astra·이동 베이스를 선택하고 회전해 볼 수 있습니다. 최신 실물 조립 상태를 재현한 모델은 아닙니다.
크게 보기 ↗2026.10.01 참고 구성 이미지 · PNG